Reinforcement Learning Related Posts
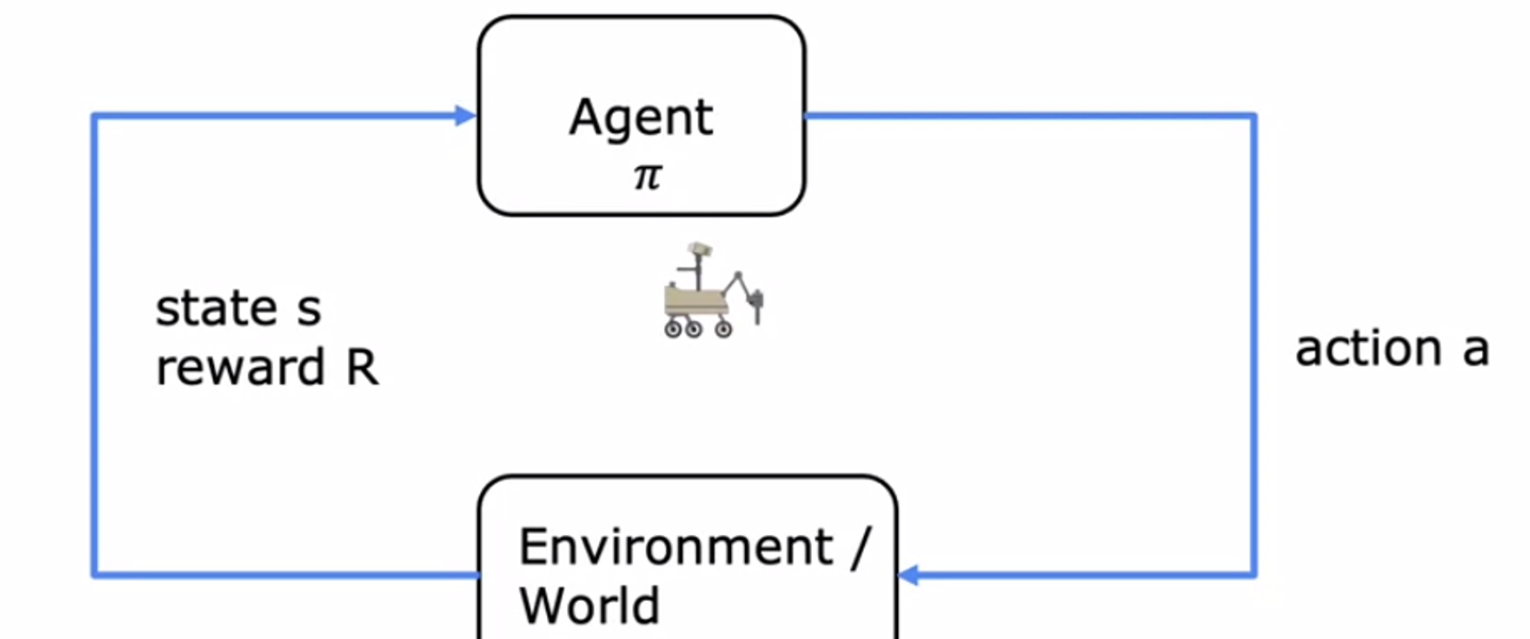
Part-1 Reinforcement-Learning - notes
This is the first part of future reinforcement learning posts and notes.
Tiny CLM: Teaching a 1.7B Model to Manage Its Own Memory for $5
Context Language Models says a model can learn to edit its own memory, and that a compute-cost reward teaches it to edit cheaply. I tested both on a 1.7B model, one GPU and $4.65. The first claim held. The second taught me something the paper didn't.
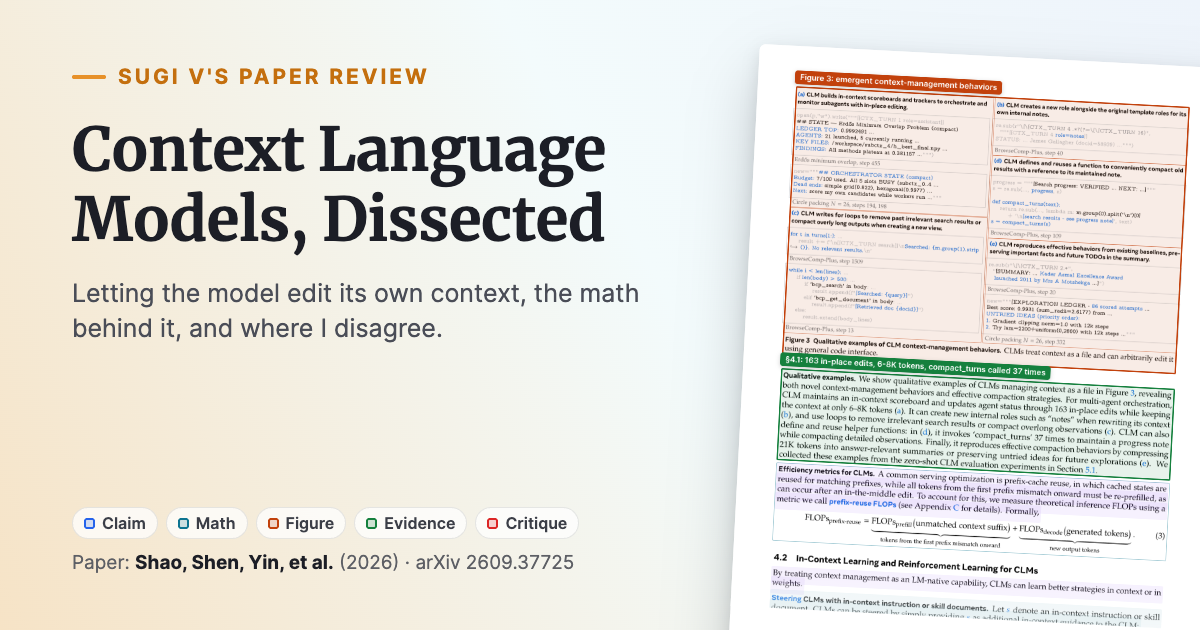
Context Language Models, Dissected: Letting the Model Edit Its Own Context, the Math Behind It, and Where I Disagree
A section-by-section review of Context Language Models (Shao et al., 2026): the formalism, prefix-reuse FLOPs, stepwise GRPO with a success-gated efficiency advantage, and Suffix Cache Reuse, with refreshers along the way.